Getting started with Videoflow
The main data structure of Videoflow is a Flow. A Flow is a directed acyclic graph (DAG) of nodes of three types — producers, processors and consumers. A directed edge from node A to node B means node B receives node A’s output as one of its inputs.
- Producer node
Producers generate data and place it on the flow. They have no parents. Examples: a node that emits a sequence of numbers, reads frames from a video file, or consumes an RTSP stream.
- Processor node
Processors receive data, compute on it, and return a result for their children.
- Consumer node
Consumers receive data and produce no output — they are the sinks of the flow. A consumer typically writes results to a file, a database, or a remote endpoint.
Prerequisite: a message broker
Nodes communicate over a NATS JetStream broker, so you need one running before a
flow can start. For local development, start it with Docker Compose (a
docker-compose.yml is included in the repository) or the nats-server binary:
docker compose up -d          # NATS on :4222, Redis on :6379
# or
nats-server -js
A first Videoflow application
This application produces integers from 0 to 40 (inclusive) at 0.1-second intervals, keeps a running sum, and prints it to the command line. See the full example in examples/simple_example2.py.
Import the nodes and wrap the graph in a build_flow() factory. The
factory returns a Flow without starting it; the same factory is used to run
locally and to deploy to Kubernetes:
from videoflow.core import Flow
from videoflow.core.constants import BATCH
from videoflow.producers import IntProducer
from videoflow.processors.aggregators import SumAggregator
from videoflow.consumers import CommandlineConsumer

def build_flow():
    producer = IntProducer(0, 40, 0.1, name='producer')
    sum_agg  = SumAggregator(name='sum')(producer)
    printer  = CommandlineConsumer(name='printer')(sum_agg)
    return Flow([printer], flow_type=BATCH)
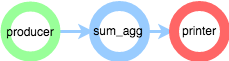
Every node is given a unique name. Processors and consumers are callable:
you call them with the parent nodes they depend on. sum_agg depends on
producer; printer depends on sum_agg. This is a simple linear graph.
Run the flow through an execution engine. LocalProcessEngine starts one
subprocess per node, each connected to the broker:
if __name__ == '__main__':
    from videoflow.engines.local import LocalProcessEngine
    flow = build_flow()
    flow.run(LocalProcessEngine())
    flow.join()
Notice that you only pass the consumers to Flow — the producers are
discovered automatically by walking the graph back from the leaves. Unlike earlier
versions, Videoflow now supports multiple independent producers in one flow.
flow.run(engine)compiles the graph and launches a worker per node (per replica, for parallel processors). It is non-blocking.flow.join()blocks until the flow finishes.
Run it (with the broker up):
python my_flow.py
# or, without a __main__ block, via the CLI:
videoflow run-local my_flow.py:build_flow --nats nats://localhost:4222
You should see a sequence of increasing partial sums printed to your screen.
Building more complex flows
Arbitrary DAGs work naturally, including fan-out (one node feeding several children) and joins (one node with several parents):
from videoflow.core import Flow
from videoflow.producers import IntProducer
from videoflow.processors import IdentityProcessor, JoinerProcessor
from videoflow.consumers import CommandlineConsumer

def build_flow():
    producer  = IntProducer(0, 40, 0.1, name='producer')
    identity  = IdentityProcessor(name='identity')(producer)
    identity1 = IdentityProcessor(name='identity1')(identity)
    joined    = JoinerProcessor(name='joined')(identity, identity1)  # a join
    printer   = CommandlineConsumer(name='printer')(joined)
    return Flow([printer])
A JoinerProcessor receives one message from each parent and emits them as a
tuple. Videoflow matches the two inputs that originated from the same upstream
event before delivering them to the join — you do not have to synchronize anything
yourself.
Complete example solutions
The solutions/ directory holds four complete, deployable applications built from core nodes only — no models, no footage, no extra dependencies:
toy_calculatorA BATCH diamond over a stream of integers: fan-out, a trace join, competing replicas, stateful aggregation and a two-parent consumer. The smallest complete solution, and the best one to read first.
toy_routerPartitioned parallelism —
partition_bypinning each key to one replica, anasync def processnode, and an idempotent sink.toy_recoveryThe error taxonomy at work: a poison message dead-lettered on first sight, a crash restarted with its un-acked messages redelivered, and a self-checking recovery report.
toy_fusionA REALTIME flow fusing independent producers by event time, with tolerance, lateness timeout, quorum and collect windows.
Each runs in seconds and writes a self-checking artifact saying whether the
distributed run computed the right answer. Name it as videoflow://<name>
and videoflow fetches it at your version (one shallow clone into
~/.videoflow/solutions/, reused afterwards):
videoflow run-local videoflow://toy_calculator
The ML solutions live in videoflow-contrib and run the same way —
videoflow run-local videoflow-contrib://human_tracking — with their stacks
inside the solution image, never on your machine. From a checkout, the path
form does the same: videoflow run-local solutions/toy_calculator/toy_calculator.py
(or just solutions/toy_calculator). The three ways to name a solution — shipped
with videoflow, cloned from another repository, on your disk — and what each
implies for the image are laid out under Prerequisites in
Deploying to Kubernetes.
Next, read Distributed execution to understand how the same graph runs locally versus on Kubernetes.